The debate everyone's having
There is a lot of argument right now about how long GPUs last. Everyone has a different number:
- CoreWeave publicly assumes ~6 years of useful life
- Nebius pegs useful life closer to 4 years
- Some analysts and investors warn it might be ~3 years or less under heavy use
- If it were up to Michael Burry, it'd probably be 6 months before the AI hardware bubble collapses
Every one of those numbers is an average, which is why every one of them is wrong for any particular card. In the telemetry we see working with lenders, identical GPUs age at very different rates depending on workload, thermals, and utilization.
Underwriting has run on averages because, until recently, averages were the only data anyone had. Now there is telemetry.
Why the old model fails
Most GPU financing deals today assume one depreciation curve for every card in the fleet. The underwriting reads something like:
That treats a GPU like a truck or an oil rig on a straight-line schedule, and GPUs do not age that way. Identical GPU hardware can age very differently depending on how it is used:
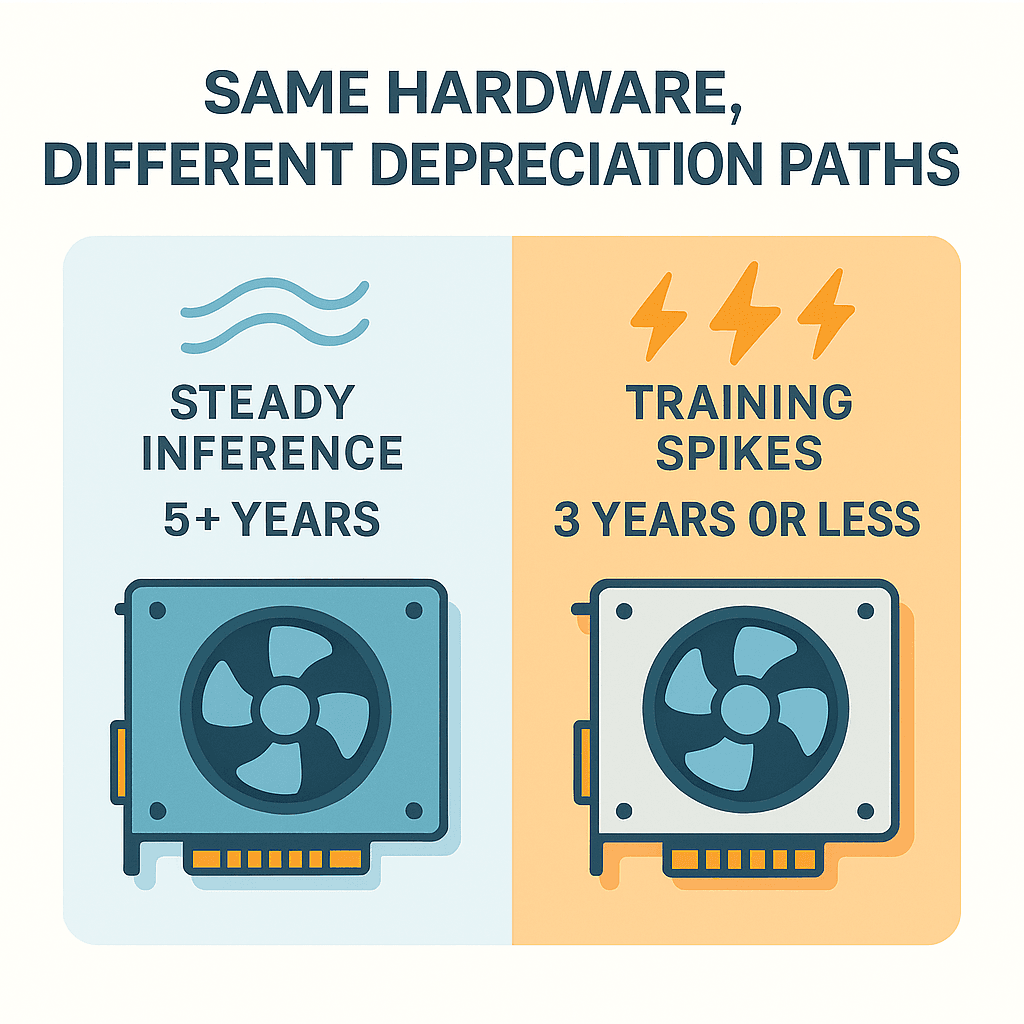
- A GPU running steady inference at 60 to 70 percent utilization, under moderate thermals, day in and day out
- vs. a GPU running irregular training workloads that spike to 95 to 100 percent utilization and push the thermal limit every afternoon
On paper these two are the exact same model of GPU. In practice their aging is nothing alike. One may still be earning its keep after 5+ years (some 2016-era GPUs are still in active cloud service), while the other is worn out, or at least no longer economical to run, in 3 years or less.
Many lenders still underwrite both the same, on one schedule, regardless of workload. That produces:
- Wrong salvage value assumptions: a heavily used GPU is worth less in 4 to 5 years than the model says
- Negative leverage: debt priced above what the asset can earn, because the cost of financing can exceed the asset's return if its life is shorter than assumed
- More lender exposure when utilization assumptions are wrong, which means holding the bag on hardware that wore out faster than the collateral schedule assumed
- Borrowers stuck with covenants and loan terms written for a fantasy workload they never ran
Financing GPUs on an average can misprice risk by a wide margin. Averages hide the extremes, and in this market the extremes are where the losses are.
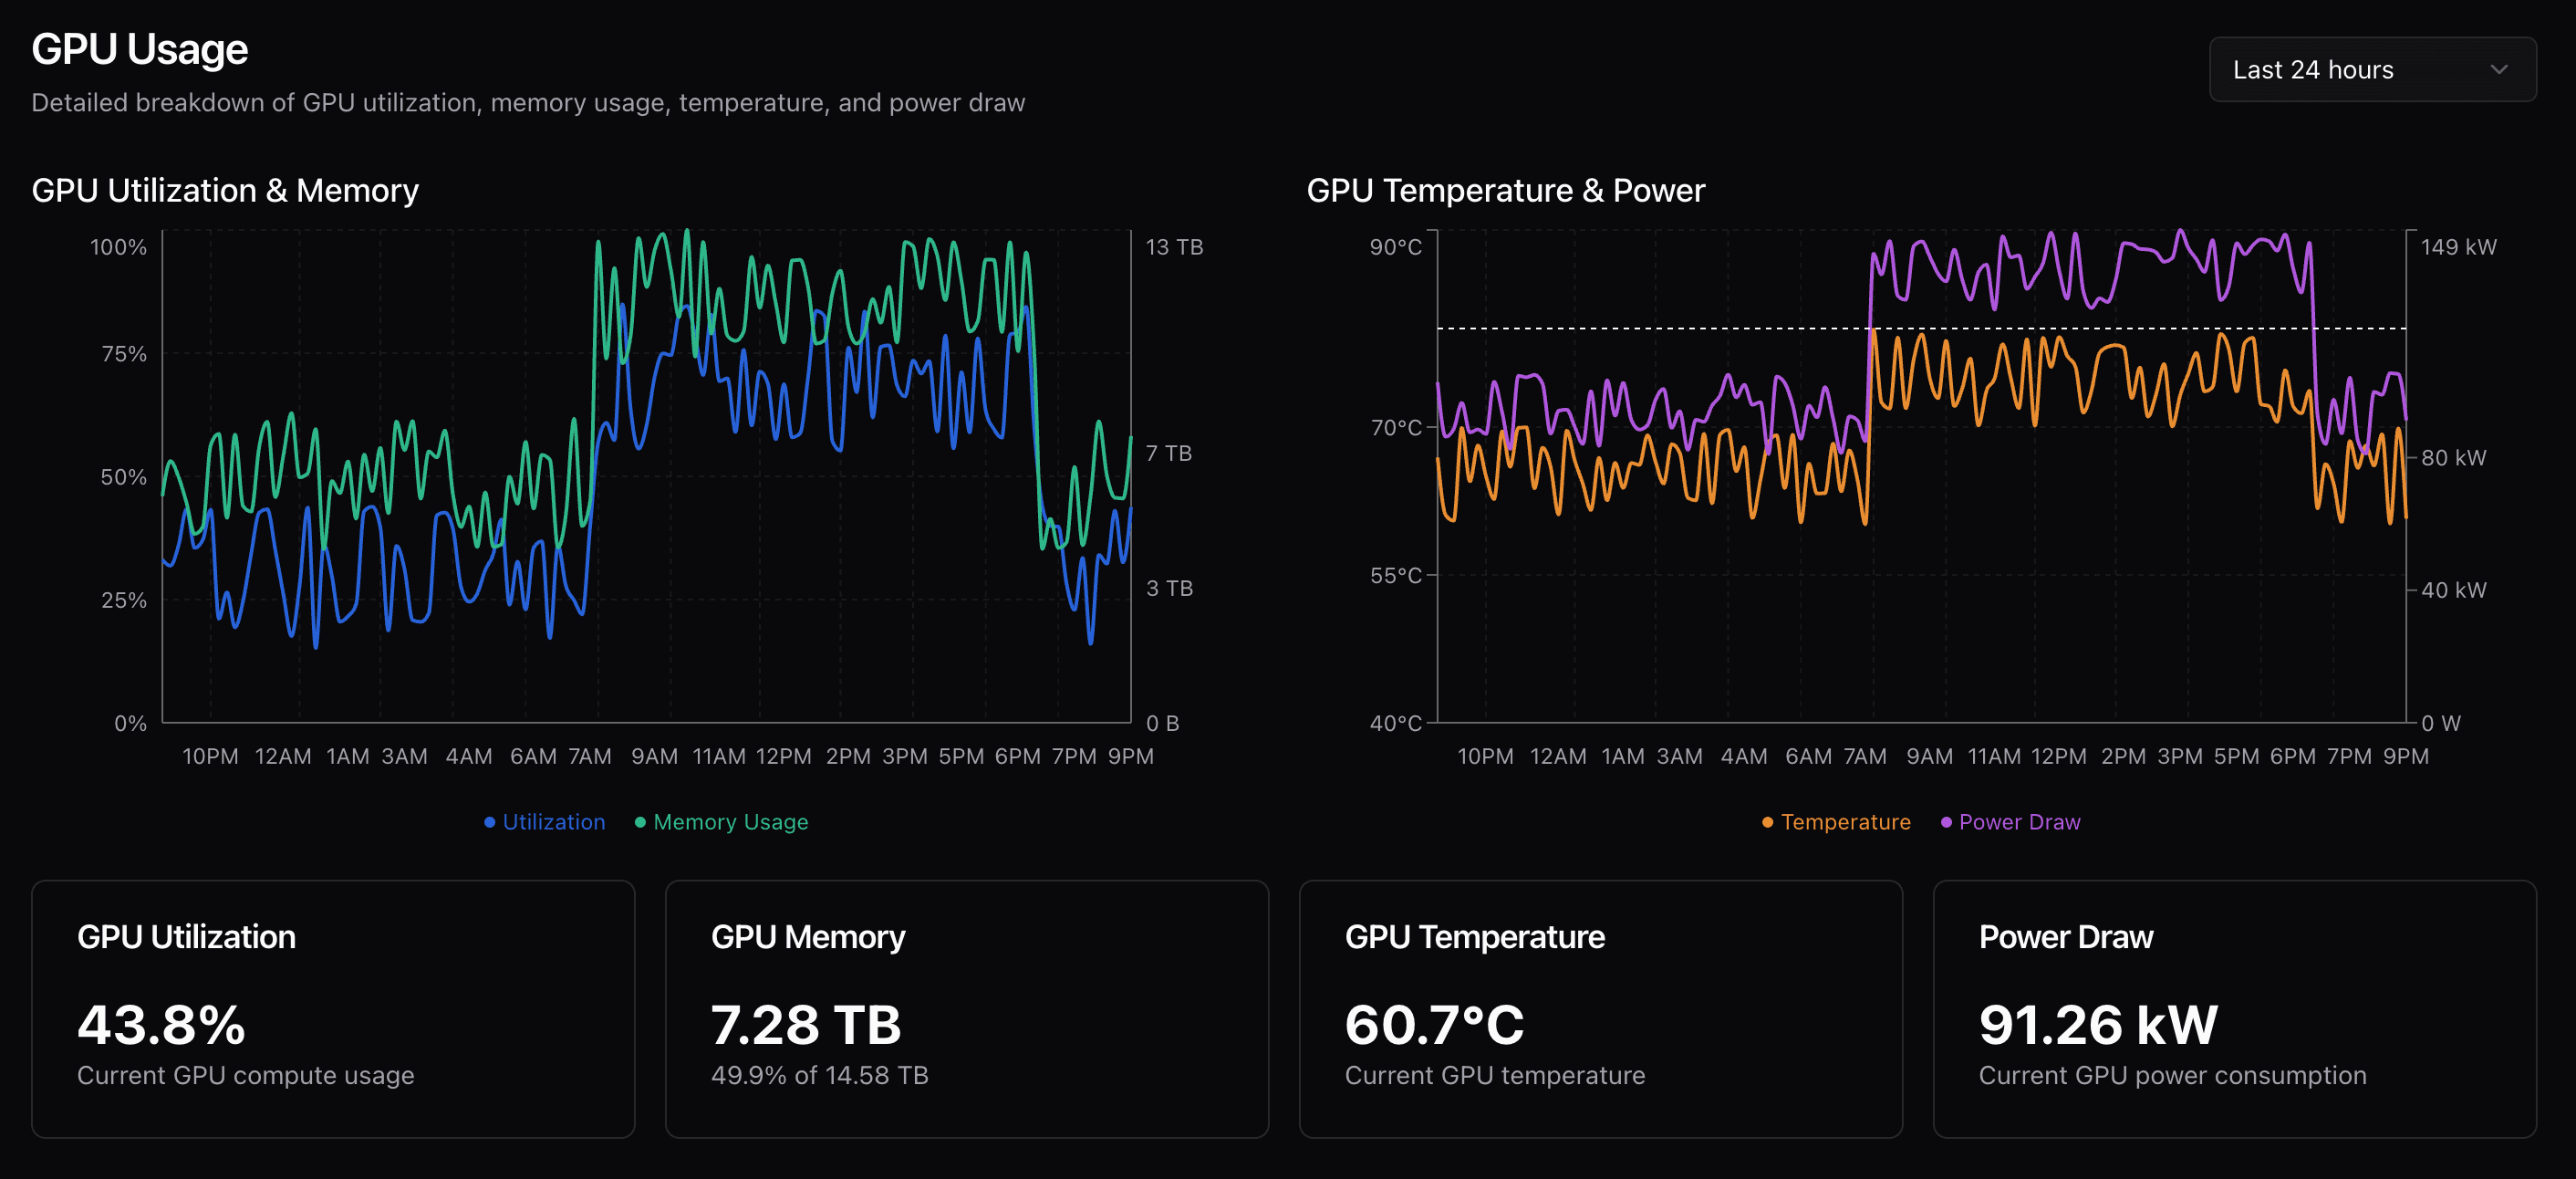
An Aravolta telemetry dashboard: GPU utilization, memory use, temperature, and power draw. Lenders and operators use this view to compare the workload they underwrote against the workload the hardware is actually running.
What we found in the field
Take a mid-market lender financing several GPU deployments in the 0 to 50 MW range, hundreds of high-end GPUs spread across multiple customers.
Their original underwriting assumed:
- ~80% steady utilization on each GPU
- ~5.5 years of useful economic life before resale or obsolescence
- No meaningful variance between customers or workload types; every GPU in the fleet was treated the same
GPU-level telemetry showed something else:
| Factor | Expected (Underwriting) | Actual Observed Impact |
|---|---|---|
| Workload intensity (spikes to 95 to 100 percent) | "Occasional" spikes assumed | Happening daily, with repeated spikes to full utilization that wear components faster |
| Thermal envelope violations | Not modeled (assumed nominal) | Frequent during training bursts. Many GPUs ran above their recommended thermal limit on a regular basis, which shortens expected life |
| Maintenance cycles (downtime, repairs) | Flat schedule (routine only) | Higher than planned under high-variance workloads. Fans, thermal paste, and other parts needed service sooner |
| Economic vs. physical obsolescence | Assumed identical timeline | Economic obsolescence ~18 to 30 months earlier for some workloads. The GPUs became too slow or too power-hungry per dollar of output long before they physically failed |
Result: the fleet's effective depreciation curve varied by 30 to 45 percent across end customers, on identical GPU models. Some customers' workloads made their hardware lose value almost half again as fast as others.
One cohort underwritten for ~5.5 years of useful life was tracking toward 3.7 years under real use. That nearly two-year gap flows through to salvage value, loan terms, covenant triggers, and the debt-to-equity mix.
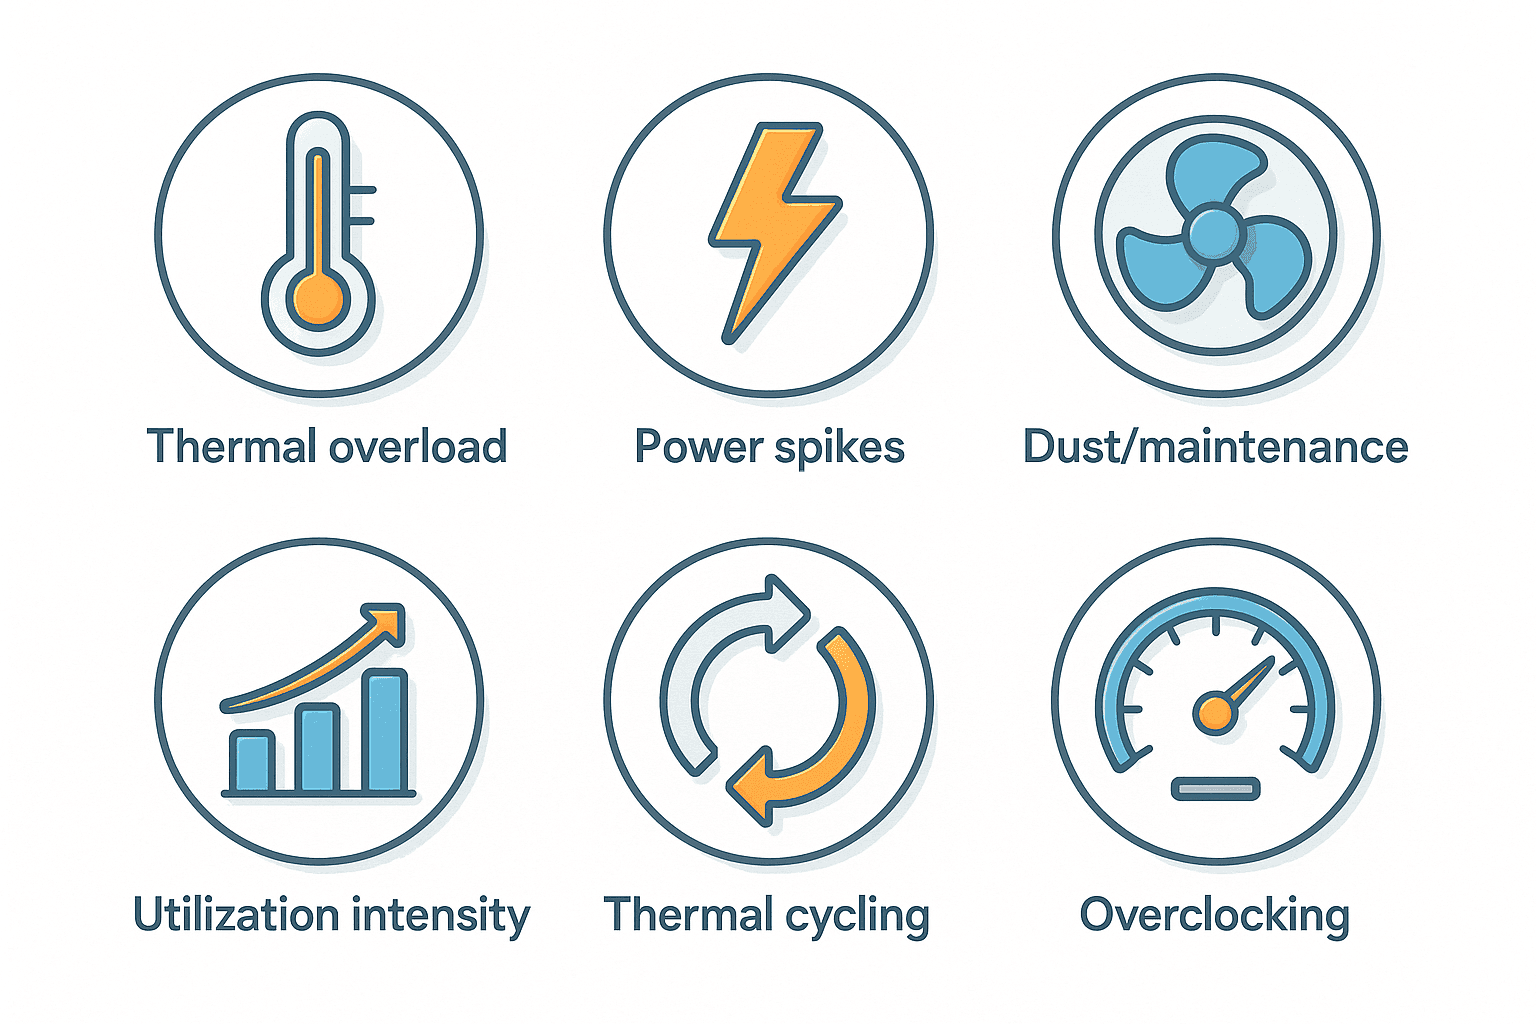
Factors and events that shorten GPU life
How fast a GPU ages, or stops performing reliably, depends on what it is put through. Thermal stress, power stress, and workload intensity matter most:
| Stress Factor | Description | Impact on Lifespan |
|---|---|---|
| Sustained High Utilization | GPU running near full capacity continuously (24/7 ~98% load) | Faster component wear. One widely reported estimate (see the Tom's Hardware citation below) gives top data center GPUs only 1 to 3 years at ~60 to 70 percent average utilization. |
| Thermal Overload | Frequent overheating events (85 to 100°C) that force thermal throttling | Large reduction in life. Each 10°C rise in operating temperature roughly halves electronic component life. |
| Power Spikes | Sudden surges in power draw or supply fluctuations | Surges strain voltage regulators and capacitors. High-end GPUs can spike past 500W, and repeated spikes cause electromigration and long-term wear. |
| Thermal Cycling | Frequent on-off cycles or large load swings | Repeated heating and cooling expands and contracts the materials and works the solder joints. Bursty workloads fail sooner than steady 24/7 use. |
| Inadequate Maintenance | Dust buildup, aging thermal paste, worn fans | Fans last ~5 years but fail sooner at constant high RPM. Clean regularly, swap fans, and renew thermal paste twice a year. |
| Overclocking/Overvolting | Running the GPU past factory specs for extra performance | Raises power draw and heat sharply. Even a small overvolt adds thermal stress. You trade a little speed now for years of life later. |
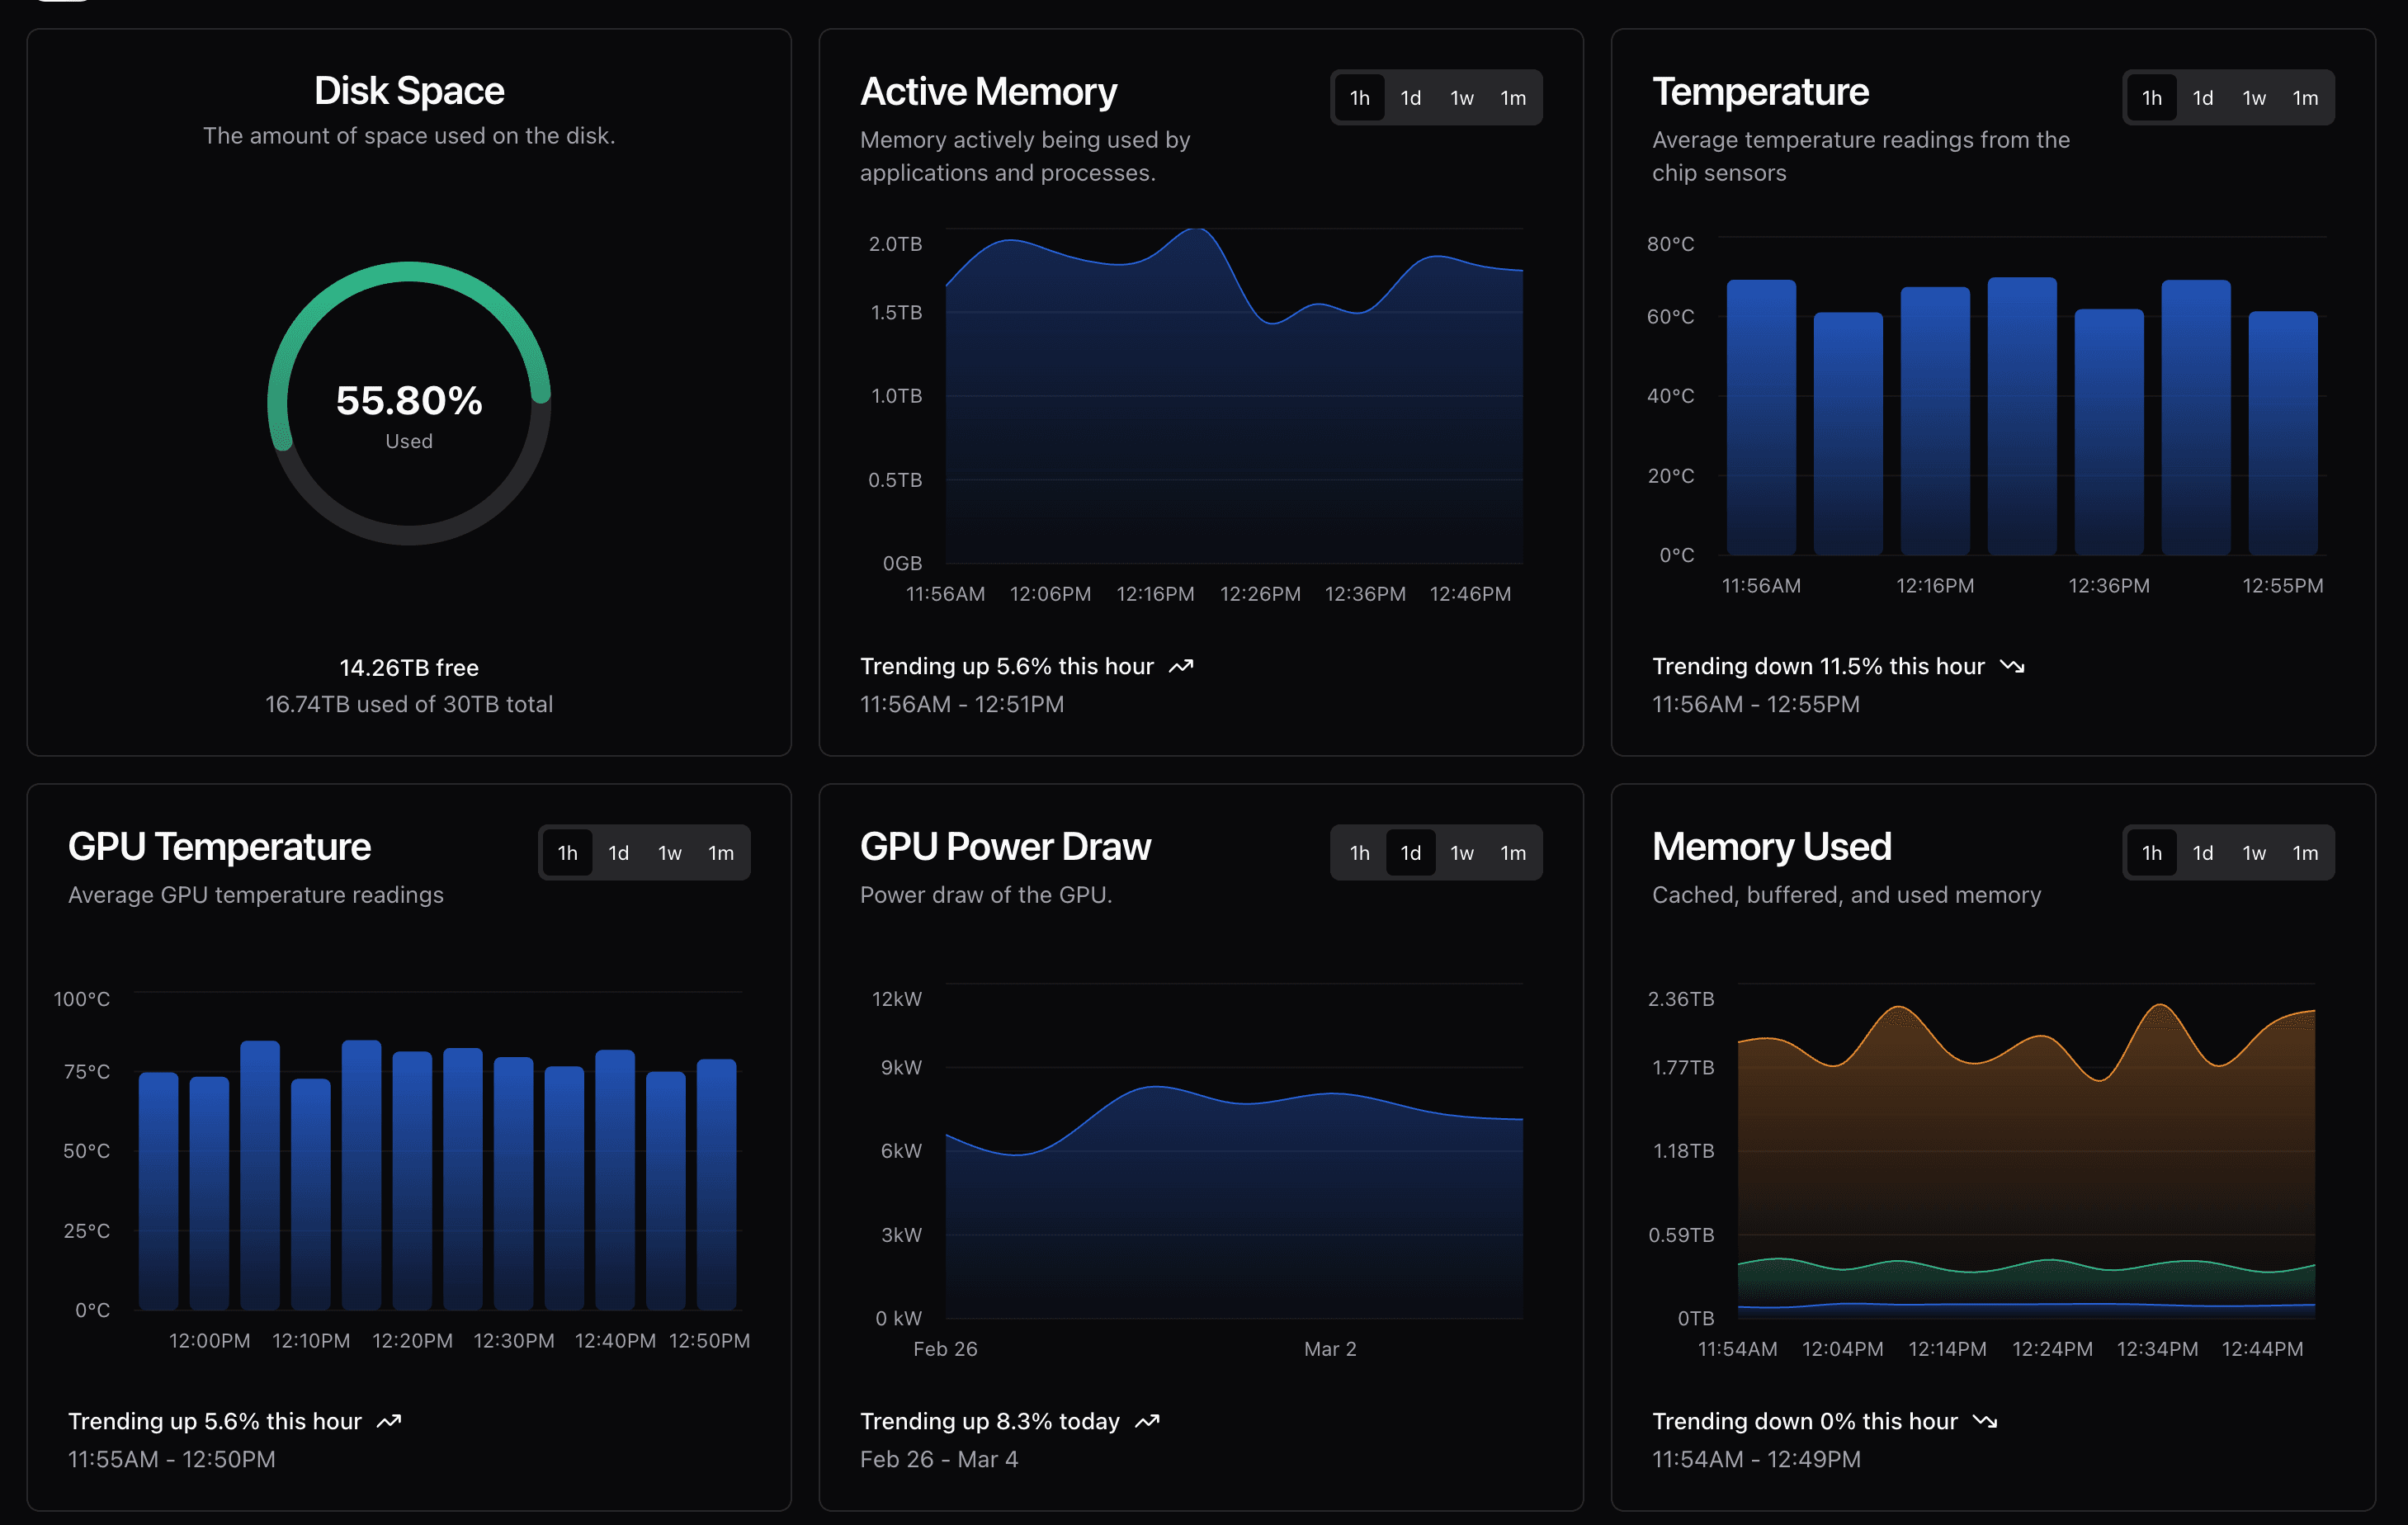
GPU health and performance metrics in Aravolta: temperature, power draw, memory behavior, and utilization over time. These traces are why identical GPUs end up with different lifespans. The card that spends its afternoons at the thermal limit shows it here long before it shows it on a balance sheet.
The pattern
The wrong question to ask about GPU longevity is:
The useful one is more specific:
Identical hardware ≠ identical useful life. Two GPUs that rolled off the same line can have very different economic lifespans depending on whether they lived a pampered life or a punishment test.
Telemetry replaces the average. Per-card data on utilization, temperature, and power draw over the life of the hardware is what tells you its real depreciation curve. It turns an argument about generalities into a measurement.
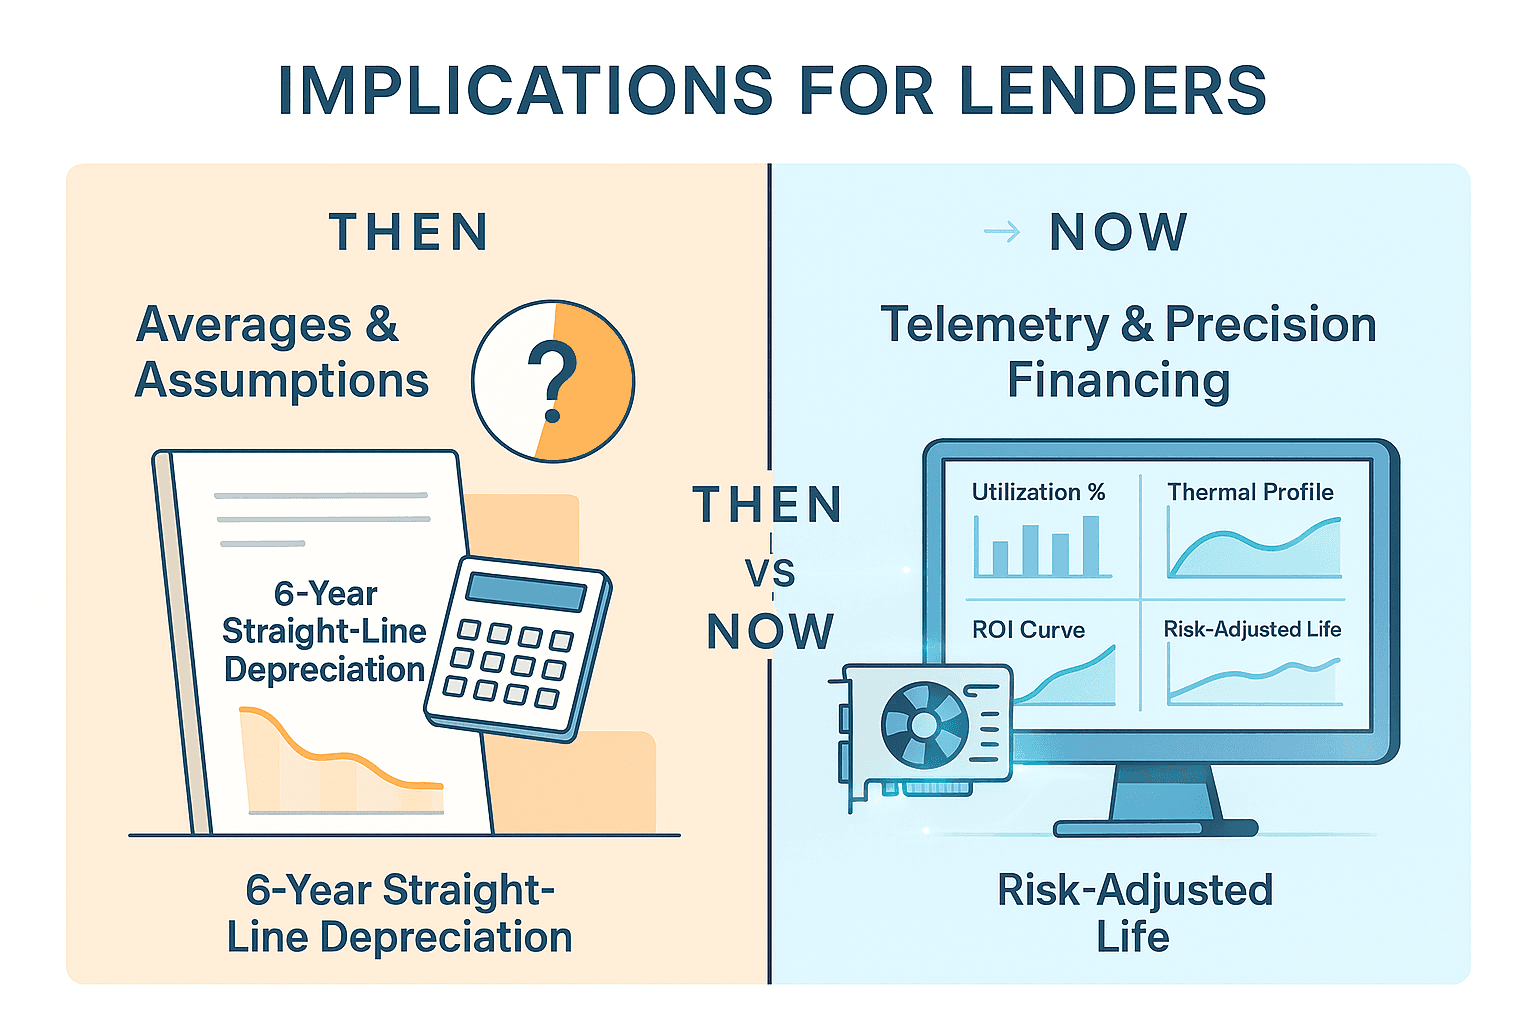
Implications for lenders
If you finance GPUs and your underwriting has no asset-level telemetry, you are probably missing the biggest risk in the category:
1. Losing principal without warning
If a borrower runs their GPUs at a constant 90 to 100 percent utilization and high thermals, the hardware can stop earning long before your model says it will. A fleet underwritten for 5 to 6 years may have 2 to 3 years of economic runway, and you find out once you are already under-collateralized and over-leveraged.
2. Overpricing some deals
You'll charge too much to borrowers who run their GPUs well. An operator with steady, moderate workloads has hardware that lasts longer, and they will notice the rate and go find cheaper capital.
3. Underpricing other deals
You'll take extra risk where GPUs are being run into the ground. Without telemetry that risk stays invisible until the write-down, and by then you are under-collateralized and under-compensated for it.
4. Leaving money on the table with deal structure
Per-card data makes structures like sale-leasebacks with performance triggers, or usage-based financing where payments track actual GPU-hours, possible. Without it you are stuck with conservative, inflexible terms.
Where things go from here
The next round of compute financing is being written right now, and it does not have to rely on folklore for GPU longevity. The tools exist to monitor GPU fleets at the hardware-signal level, in real time, and produce real depreciation curves per workload and environment instead of one per SKU.
We're working with lenders and mid-market operators (the 1 to 100 MW segment) on sale-leasebacks, usage-based leases, and revolving GPU credit lines, all priced off measured performance. It is lending on actual risk, not averages.
Frequently asked questions
How long do data center GPUs typically last?
There is no single answer. Identical GPUs can have very different lifespans depending on workload, utilization, and thermal management. Some companies assume 4 to 6 years of useful life, but a heavily used GPU running training workloads may only stay economically viable for 2 to 3 years.
What factors most affect GPU lifespan in data centers?
Sustained high utilization (near 100% load), thermal overload, power spikes, thermal cycling from bursty workloads, and poor maintenance. Each 10°C rise in operating temperature roughly halves electronic component life.
Why do identical GPUs age differently?
A GPU running steady inference at moderate utilization and thermals can last 5+ years. An identical model running irregular training workloads that spike to 95 to 100 percent utilization may wear out in 3 years or less. How the card was used determines its life as much as the spec sheet does.
What is the problem with average depreciation assumptions?
An average treats every GPU the same regardless of workload, so it hides the extremes. The result is wrong salvage value estimates, mispriced risk for lenders, and loan terms that do not match how the asset actually performs. In one fleet we measured, the effective depreciation curve varied by 30 to 45 percent across customers on identical GPU models.
How does telemetry improve GPU financing?
Telemetry gives the lender per-card utilization, temperature, power draw, and maintenance history, so underwriting can price the actual risk instead of an industry average. That supports a depreciation curve per workload and structures like usage-based leases.
What did Aravolta observe in real GPU deployments?
In mid-market fleets underwritten for ~5.5 years of useful life, telemetry showed daily utilization spikes to 95 to 100 percent, frequent thermal limit violations, and more maintenance than planned. Some cohorts were tracking toward 3.7 years of effective life, nearly two years short of the assumption.
What maintenance do data center GPUs require?
Regular cleaning, fan replacement (fans last ~5 years but fail sooner at constant high RPM), and thermal paste renewal, recommended twice a year. Skipping any of it speeds up wear, especially under heavy workloads.
How do training workloads differ from inference for GPU longevity?
Training tends to spike the card to maximum utilization and push it against its thermal limit, and the resulting thermal cycling wears components faster. Steady inference at moderate utilization (60 to 70 percent) is far easier on the hardware, and the card lasts longer.
Last updated: March 2026